 How Motive migrated from Opsgenie and achieved 99.99% reliability with Rootly.
 Paul van Liew
Keep your team coordinated from first alert through the retrospective, with AI that actually helps—not just summarizes what happened.



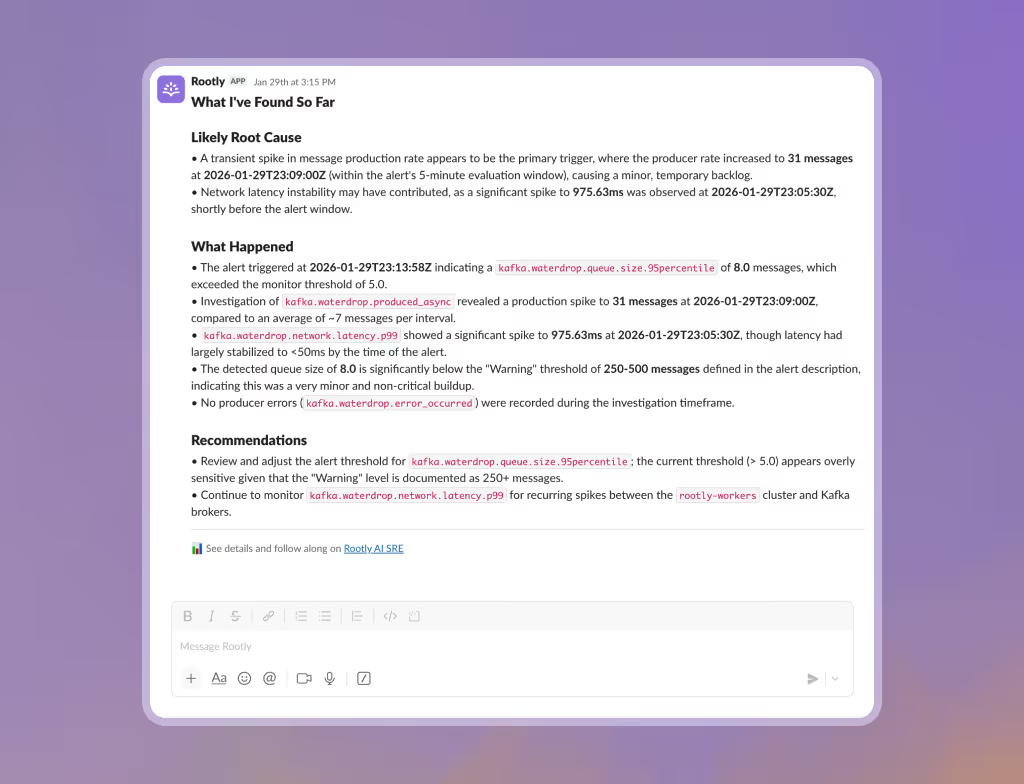
Declare incidents, assign roles, page responders, update stakeholders, and run the full response—directly from Slack or Teams.
Schedules, escalation policies, alert routing, rotations, holiday calendars, and live call routing—built to get the right person paged, once.
Retrospectives that generate from the full incident context—no manual reconstruction, no blank page.
AI that correlates alerts, surfaces root cause with confidence scores, drafts status updates, responses to any queries—while your team is in the incident or looking for info about past incidents.
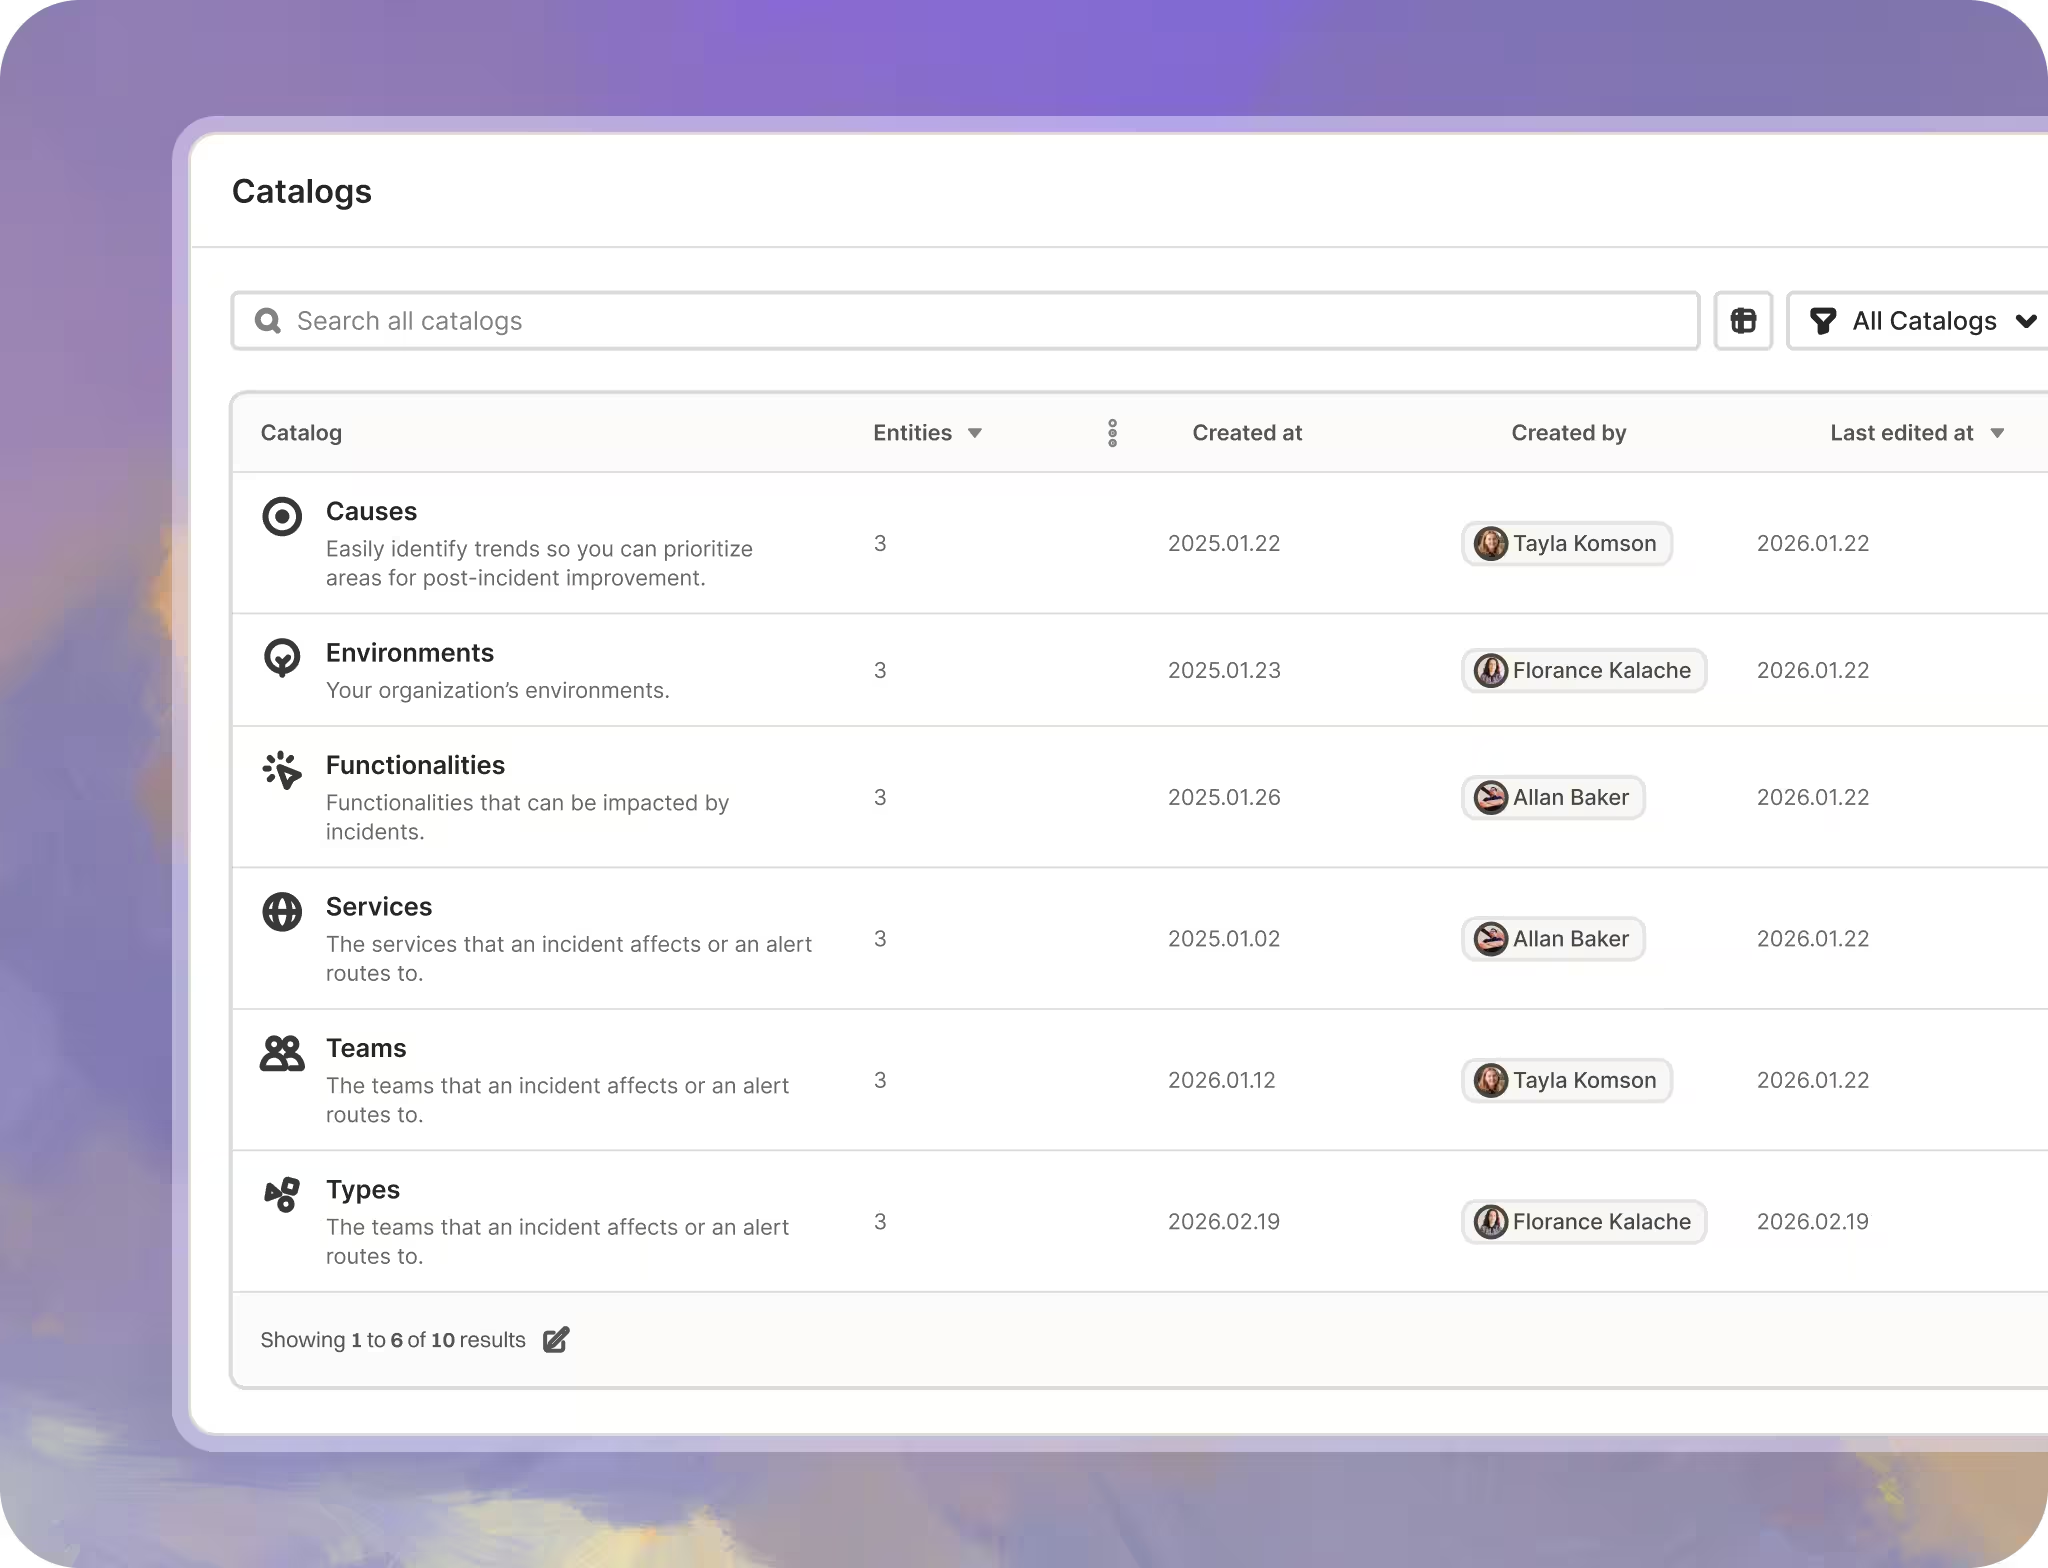
Service catalogs connect your services, teams, runbooks, and dependencies directly to every incident—so responders know what's affected and who owns it, without leaving Slack or Teams.
It connects your entire organization for unmatched context and flexible workflow customization.
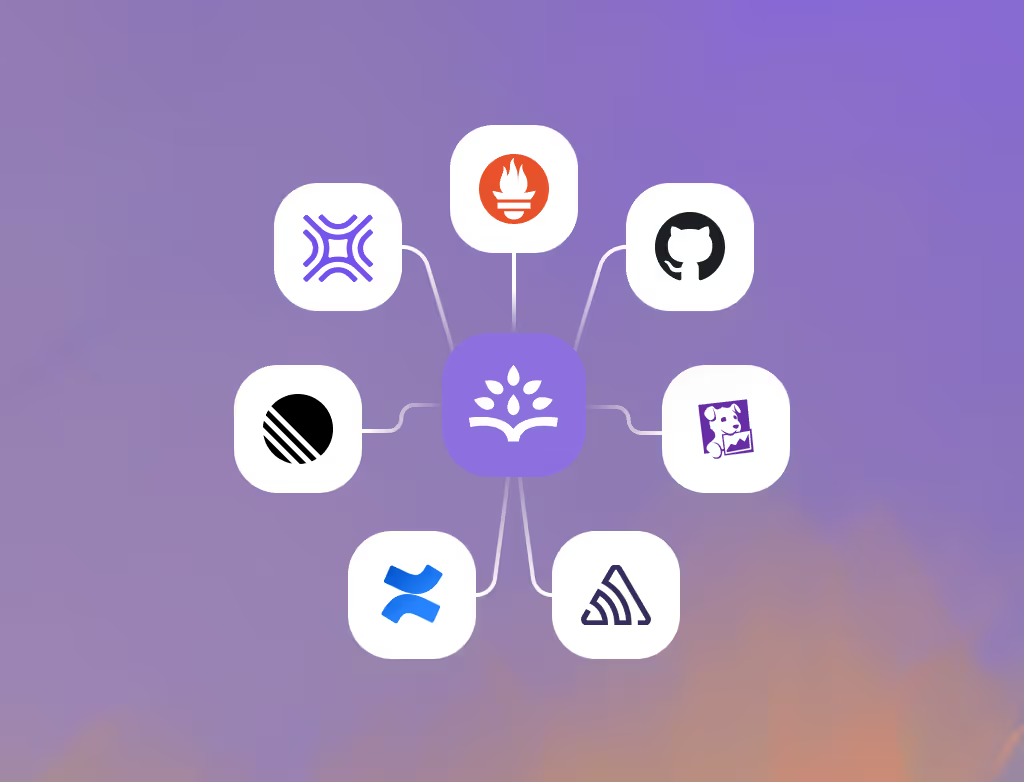
100+ integrations including Datadog, GitHub, Jira, Grafana, New Relic, Sentry, Terraform, Linear, and more—Rootly pulls in observability context and pushes updates automatically, so you spend time resolving, not copy-pasting or searching.
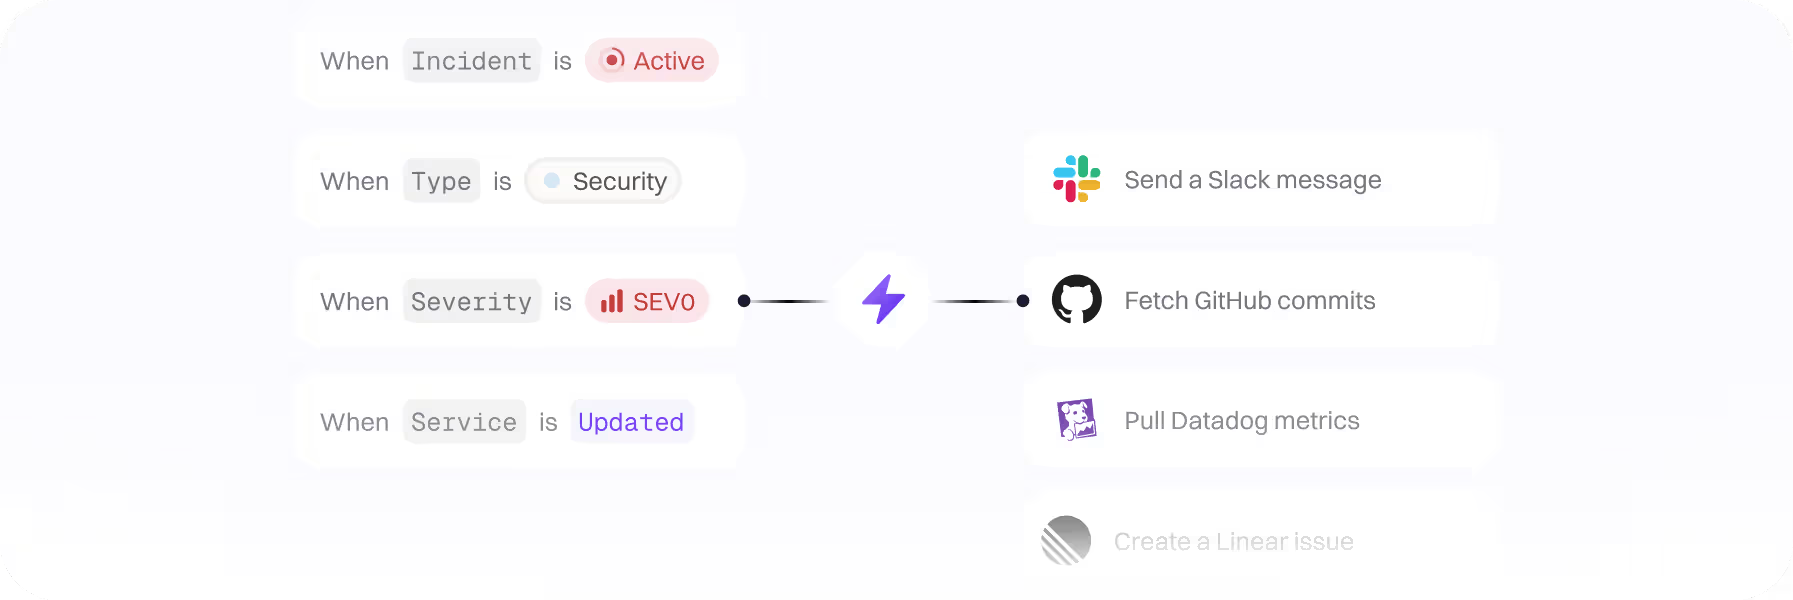
Every minute of downtime has a cost. Rootly gets the right people paged, context assembled, and response coordinated in the first five minutes — before the incident compounds.
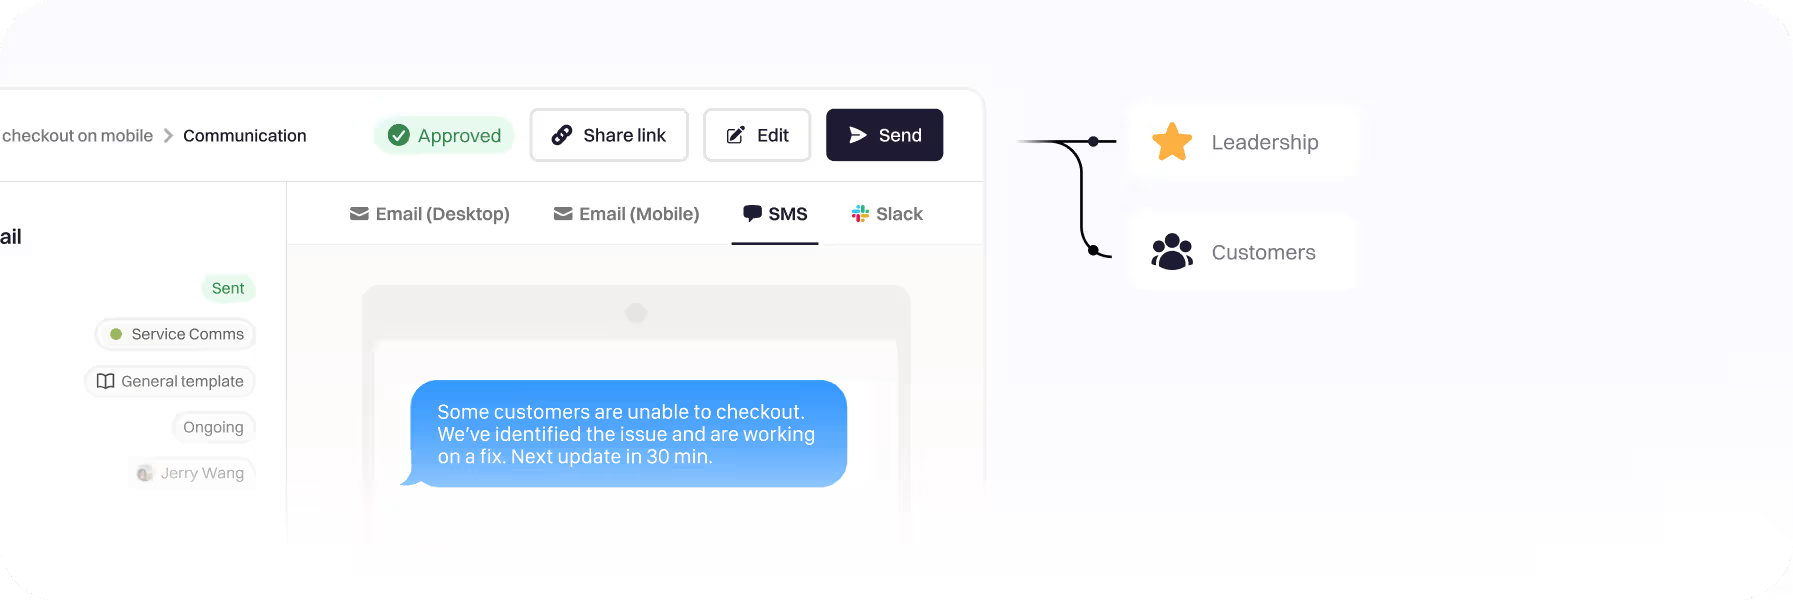
Rootly handles stakeholder communication during an incident — status page updates, internal notifications, and audience-specific updates generated by AI — so your responders stay focused on the fix, not the inbox.
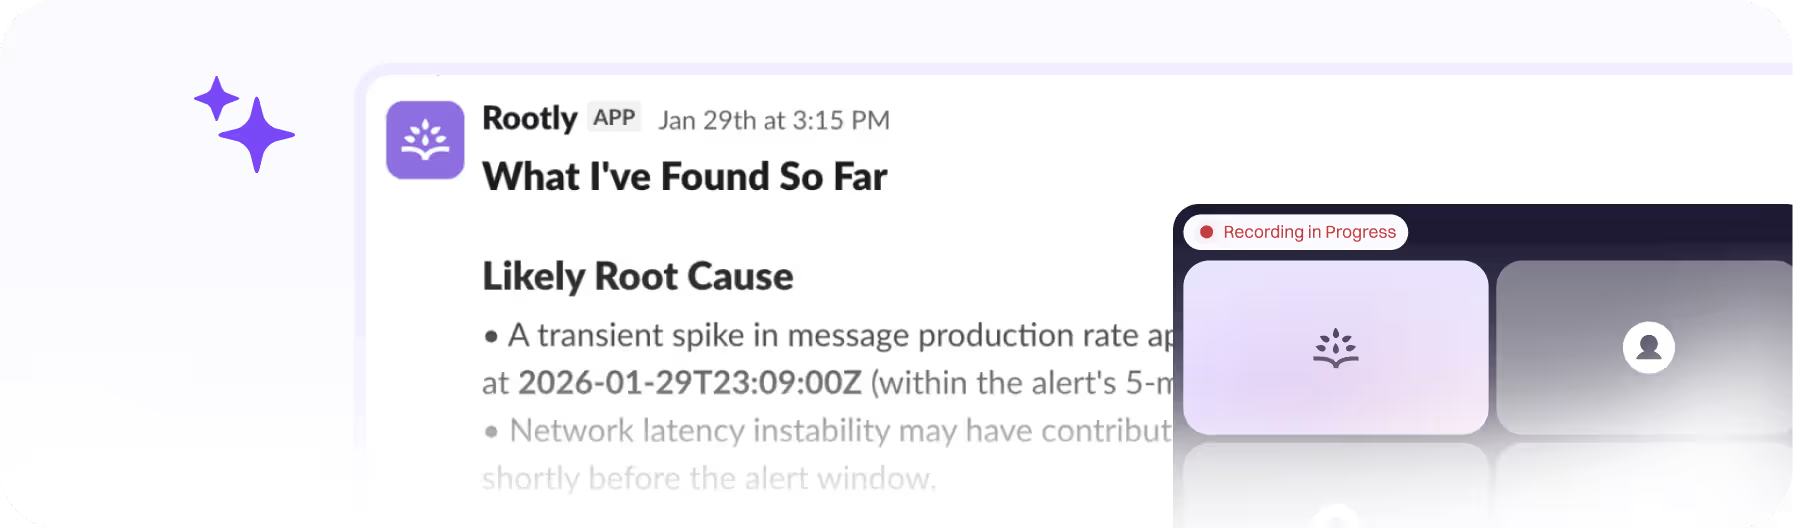
Rootly AI joins your incident calls, takes notes, captures decisions, and tracks action items in real time — so nothing gets lost between the call and the retrospective.
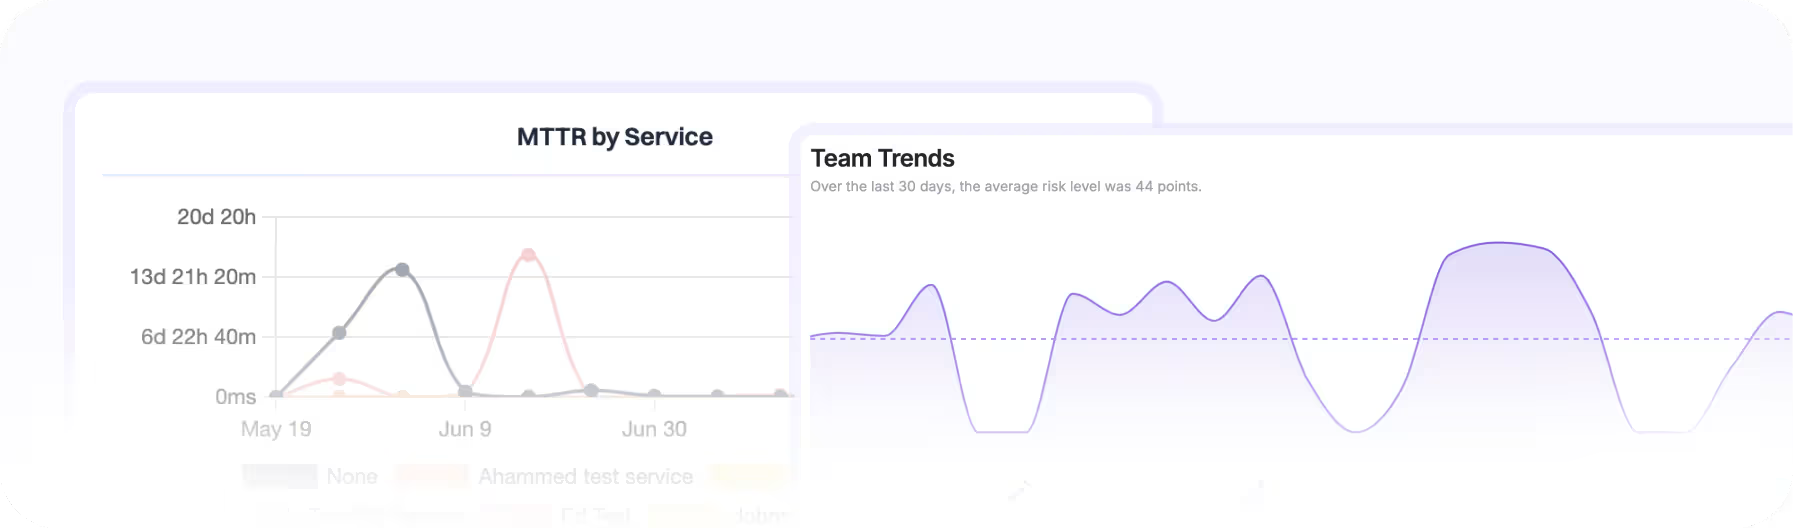
MTTR, repeat incident rate, alert volume by service, on-call load by engineer — Rootly surfaces the metrics that show where your reliability debt is accumulating, so engineering effort goes to the right place.
 How Motive migrated from Opsgenie and achieved 99.99% reliability with Rootly.Paul van Liew
 Clay switched off Opsgenie to use Rootly to streamline incident management.
 George Dilthey
 Replit brings structure, speed, and better decision-making to incident response with Rootly.
 Matthew Iselin
 Achievers switched from PagerDuty and productized reliability on Microsoft Teams with Rootly.
 Stefan Kolesnikowicz