The Reliability Top 50 · 2026

The people making the world
more reliable.

Behind every system we depend on, there are people making it work around the clock.

An illustrated world connected by reliable transport, energy, and communities.

The agentic future depends on people.

AI agents are moving from answering questions to taking action: writing code, investigating incidents, and changing the systems we depend on. Every new capability brings an operational question. What happens when an agent gets it wrong? How do we see what it did, contain the damage, and recover?

The people on this list are doing the work that makes those questions answerable. They build dependable infrastructure, make production behavior understandable, and share what failure teaches them. Their contributions give us the foundations to put more capable systems into the world with greater confidence.

As we give software more autonomy, I believe the judgment and generosity of this community become even more valuable. The Reliability Top 50 celebrates the people building that future—and making sure the rest of us can learn from it.

JJ Tang
Co-founder and CEO, Rootly

Making AI reliable

People exploring AI in production and defining where it helps, where it fails and what it needs to work reliably.

Michelle Brush

Michelle Brush

Engineering Director, SRE-SWE

More generated code means more behavior for engineers to understand. Michelle brings that challenge into focus from Google, where she leads global SRE teams responsible for Compute Engine and Persistent Disk, systems on which other teams build their own production services.

Her keynote Taming the Unpredictable: Reliability in Chaos examines rigorous evaluations, generic mitigations, reproducibility and designing around risk as system complexity grows. A contributor to 97 Things Every SRE Should Know, she connects those practices with a consistent concern: keeping human judgment central when software becomes harder to predict.
Mario Fahlandt

Mario Fahlandt

Customer Delivery Architect

Customer delivery at Kubermatic and participation in the CNCF Technical Oversight Committee give Mario perspectives on both operating Kubernetes and shaping its wider ecosystem. His public work connects troubleshooting practice with the emerging demands of AI workloads.

In his KubeFM discussion of Kubernetes AI conformance, guardrails become a concrete operational topic. His explanations also examine where AI-assisted diagnosis sends collected data and how backend choices affect that path, giving teams questions to ask before adopting another diagnostic tool.

Brendan Gregg

Brendan Gregg

Member of Technical Staff

Performance numbers depend on the system around the hardware. Now working at OpenAI, Brendan brings a performance engineer’s attention to the software, tuning and workload choices that can change what a benchmark appears to say.

In Third Stage Engineering, he examines those interactions rather than treating hardware comparisons as self-explanatory. His contribution is the investigation itself: showing engineers which assumptions to inspect before turning a performance result into an infrastructure decision.

Michael Kehoe

Michael Kehoe

Production Engineering Lead

Running cloud infrastructure connects architecture decisions with the people who operate the resulting systems. Michael brings experience in incident response, disaster recovery, and cloud platforms to his production engineering leadership at CoreWeave, following roles at LinkedIn and Confluent.
As co-author of Cloud Native Infrastructure with Azure, he makes that engineering discipline accessible through practical guidance on infrastructure as code, Kubernetes, observability, and networking. His contribution spans building infrastructure and helping other engineers understand the operational choices beneath it.

Moosa Khalid

Moosa Khalid

Site Reliability Engineer

Turning an idea into running software is getting faster. Keeping that software dependable still takes operational judgment. As an SRE at Replit, Moosa brings that perspective to a platform where AI helps people build and deploy applications. His background connects the infrastructure beneath a service with the incident response needed when its behavior becomes unpredictable.

He developed that experience at Netflix and Workday: coordinating high-severity incident response across Netflix’s global engineering teams, operating production Kubernetes workloads at Workday, and designing more repeatable delivery through GitOps. That combination of production troubleshooting, automation and recovery experience informs the reliability practice he brings to Replit as the path from an idea to a live application continues to shorten.

Effie Mouzeli

Effie Mouzeli

Senior Site Reliability Engineer

Caching keeps the web fast until traffic stops behaving the way its designers expected. At the Wikimedia Foundation, Effie works on the infrastructure behind Wikipedia, bringing that operational perspective to the pressure that large language model traffic places on shared online resources.

Her SREcon session, Fifty Shades of Caching and How LLMs Paint It Blαck, follows caching from edge delivery to application memory through practical, open-source examples. By explaining both the mechanisms and their changing workloads, she makes a growing AI infrastructure problem accessible to the engineers responsible for keeping the web available.

Arnaldo Sepulveda

Arnaldo Sepulveda

Independent Applied AI Engineer

Keystone Applied Intelligence

More than twelve years at Genesys put Arnaldo close to the realities of enterprise contact-center systems: integrations, migrations, production incidents, and the handoffs between technical teams. He now draws on that experience in his independent applied AI work under Keystone Applied Intelligence.

His reference implementations address authorization-aware retrieval, conversational workflows, and evaluation. They carry familiar operational concerns into AI systems: which information a model can access, when a workflow should hand control to a person, and how to retain evidence when a test fails.

Martin Smith

Martin Smith

Principal Architect, Site Reliability, DGXC Cloud

For NVIDIA’s GPU infrastructure, available hardware and usable capacity are not always the same thing. Martin brings more than two decades of reliability and cloud infrastructure experience to DGX Cloud, connecting engineering teams with the cloud providers their systems depend on.

His SREcon Americas 2026 session with Abe Hoffman draws on operating multi-region GPU fleets at a scale of more than 10,000 GPUs. By examining hardware variation, firmware, and orchestration, they give engineers practical ways to assess the capacity and failure behavior behind AI infrastructure.

Designing for failure

People uncovering how systems fail and designing them to recover.

Marc Brooker

Marc Brooker

VP/Distinguished Engineer

An operation has failed. What the system does next is an engineering decision with consequences for everything around it. Marc explores those decisions in his distributed-systems writing alongside his work as a distinguished engineer at AWS.

What Now? Handling Errors in Large Systems makes error handling an explicit part of system design. By examining the choices after a failure, he gives engineers a sharper way to reason about whether their response will contain a problem or pass it along.

Aleksey Charapko

Aleksey Charapko

Associate Professor

University of New Hampshire

Recovery is supposed to end a failure. Aleksey studies the uncomfortable cases where it helps keep one going, bringing his distributed-systems research at the University of New Hampshire to problems engineers encounter in production.

His explanations trace how recovery mechanisms interact with overload, feedback loops and accumulated work. That perspective encourages teams to inspect the behavior of their recovery path as carefully as the original failure, especially when a backlog makes every attempt to catch up more expensive.

Chris Down

Chris Down

Production Engineer, Reliability Foundation

Meta

Linux memory management sits beneath many production symptoms, yet advice about it often loses the workload context. Chris brings that detail back into view alongside his work in Meta’s Reliability Foundation organization.

His examination of zswap and zram follows the tradeoffs into kernel behavior and supporting references. The result helps engineers reason about their own systems instead of applying a universal setting to workloads with very different constraints.

Nikhil Gupta

Nikhil Gupta

Senior Engineering Manager

An availability estimate is only as sound as its assumptions about dependencies. Working across change, release, observability and AIOps at ING, Nikhil brings that question to his writing about AI reliability planning.

He examines correlated failures and shared failure domains, showing why simple availability arithmetic can hide important relationships. Making those assumptions explicit gives engineers a more useful starting point for discussing what their systems can actually depend on.

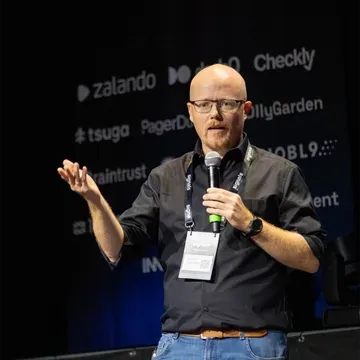
Dane Knecht

More than 20% of the web sits behind Cloudflare’s network, making its operational failures consequential well beyond the company. As CTO, Dane has helped make those failures inspectable through public postmortems, including the December 5, 2025 incident that affected roughly 28% of Cloudflare’s HTTP traffic.

The follow-up Code Orange: Fail Small plan connects those incidents with changes to rollout controls, failure gates and service dependencies. Publishing the mechanisms and the proposed response gives other infrastructure teams concrete decisions to examine when considering how far a single change can spread.

Philip O’Toole

Philip O’Toole

Creator and Maintainer

rqlite

A distributed database built on SQLite has to connect local storage behavior with replication and recovery. As rqlite’s creator and maintainer, Philip works directly with that boundary and explains the decisions beneath the familiar database interface.

Taking control of the SQLite WAL follows the write-ahead log into those design choices. Opening up that implementation detail helps engineers understand how persistence and replication fit together, and why the relationship matters when a system has to recover.

Todd Palino

Todd Palino

Senior Staff Engineer

Reliable data delivery depends on details that are easy to hide behind a streaming API. As a co-author of Kafka: The Definitive Guide, Todd helps engineers work through replication, producer acknowledgments, consumer behavior, and the monitoring needed to run Kafka in production.

His engineering experience at LinkedIn and Affirm gives that guidance an operational foundation. Across the book’s treatment of delivery guarantees, configuration, and failure handling, he helps readers connect how Kafka works with the checks its operators need to establish that data is moving reliably.

Daniel Stenberg

Daniel Stenberg

Founder and lead developer

The cURL project

For curl’s founder and lead developer, reliability includes the quiet maintenance that users may never notice. Daniel’s writing opens up the work of keeping this widely used piece of internet infrastructure healthy as it continues to change.

His account of curl performance explains how contributors track regressions while dealing with noisy measurements. By showing the checks and collaboration behind a result, he makes long-term software maintenance a practice other projects can learn from.

Learning from incidents

People guiding teams through incidents and turning experience into better practices.

John Allspaw

John Allspaw

Co-founder

Adaptive Capacity Labs

An incident forces people to build a shared picture while the situation keeps changing. At Adaptive Capacity Labs, John studies that work through human factors, resilience and the decisions teams make under pressure.

His writing on cognitive systems engineering considers how incident support can serve shared understanding, while his SREcon discussions invite practitioners to examine how learning happens. The focus stays on helping people make sense of an evolving event, with tools designed around that work.

Heather Arbore

Heather Arbore

Director of Information Technology

An incident program needs people who can carry a response through resolution and turn its aftermath into follow-through. At Zillow, Heather is building that organizational capacity through her IT leadership, with incident management and problem management treated as connected responsibilities.

Her public descriptions of the team’s work make those responsibilities concrete: leading incident calls, assigning follow-up actions, spotting recurring issues and extending coverage across time zones. The emphasis is on a practice that continues after service is restored, with cross-team relationships and clear ownership helping the organization act on what incidents reveal.

Andreas Deuschl

Andreas Deuschl

Senior Director SRE

Dynatrace

A near miss may never trigger a formal postmortem, but it can still reveal how a system really works. Leading SRE at Dynatrace, Andreas brings that wider view to his talks on incident learning.

He makes room for ambiguous failures and problems that stop short of becoming major incidents. Looking at those experiences gives teams more opportunities to learn from everyday operations, including the moments when people successfully prevent a situation from getting worse.

Fred Hebert

Fred Hebert

Principal Engineer

Automation changes the work people do, often in unexpected ways. Through his articles and engineering work at Honeycomb, Fred connects software behavior with human factors and organizational decisions, helping engineers understand what keeps complex systems dependable.

In Embracing the Code Review Bottleneck, he shows how his team used reviews of plans and AI-generated code to build shared understanding. His writing on Private Cloud automation extends that approach to managing change: giving engineers clearer signals and inspectable tools so they can keep ownership as more work is automated.

Maggie Hewitt

Maggie Hewitt

Head of Site Reliability Engineering

Duolingo

Search-and-rescue volunteering gives Maggie a second setting in which coordination under pressure matters. She brings that experience into conversations about operational leadership alongside leading site reliability engineering at Duolingo.

Her account of long-running incidents connects command structure, task ownership and shared situational awareness. The lessons cross domains while staying practical: keeping a response organized as time passes and making sure the people involved understand the situation they are working in.

Lorin Hochstein

Lorin Hochstein

Staff Software Engineer

An incident timeline can record the sequence without explaining why people’s decisions made sense at the time. In Surfing Complexity, Lorin explores that missing context alongside his software engineering work at Airbnb.

Essays such as How the incident happened: a play in one act use storytelling to reveal the pressures around operational work. His SREcon session The Power of Stories carries that approach into the community, helping teams learn from incidents without reducing them to one person’s mistake.

Tim Irving

Tim Irving

Lead Technical Duty Officer

Experience with incident command and post-incident reviews at Atlassian informs Tim’s work as a technical duty officer at Xero. On his blog, Zero Sev Zero, he brings that operational background to the preparation and communication an effective response depends on.

His essays treat incident response as something an organization builds before the outage starts. Rehearsal and shared expectations give the discussion practical weight, helping teams consider how they will coordinate when an unfamiliar problem puts their normal routines under pressure.

Ben McBratney

Ben McBratney

Head of Incident Strategy

More than a decade building and running incident programs at Braintree, PayPal, and Chime gives Ben a practical view of what teams need when systems fail. Now leading incident strategy at Rootly, he shares that experience through guidance on declaring incidents, assigning clear roles, and making decisions while the facts are still emerging.

His writing brings the same attention to what happens after recovery: understanding the conditions behind an incident, asking what made responders’ decisions reasonable, and choosing follow-up work teams can actually complete. His approach to AI keeps those conversations central, using automation to assemble timelines and surface evidence while people work through what they have learned.

Scott Nelson Windels

Scott Nelson Windels

Incident Program Manager

An incident program depends on people who know how to work together under pressure. Scott brings that focus to Notion after building Slack’s incident-response ecosystem and training more than half of its engineering organization.

His SREcon Americas 2026 discussion with Andrew Hatch extends that experience to management and mentoring in SRE. Connecting operational practice with how engineers develop and lead teams makes reliability a capability people can build together, supported by the experience of establishing incident programs across organizations.

Making sense of production

People making complex systems easier to observe, debug and improve.

Maren Afflerbach

Maren Afflerbach

Software Development Engineer 3

Before a legacy system can be safely replaced, someone has to discover what it actually does. At SIXT, Maren tackles that problem in a 25-year-old monolith where PHP and COBOL share database connections across more than 200 modules and 10,000 tables.

Her account of building observability for that system gets into SQL fingerprinting, cross-language stack traces, custom parsers and runtime ownership mapping. Implementing OpenTelemetry where official language support is missing makes the work especially concrete. The resulting visibility changed the team’s decomposition strategy, turning modernization from an architectural assumption into a decision informed by production behavior.

Frederic Branczyk

Frederic Branczyk

VP of Data Engineering

Understanding where software spends its time has shaped Frederic’s work as the founder of Polar Signals and creator of Parca. Now leading data engineering at Dash0, he brings that experience building continuous profiling tools to a broader observability platform.

His recent articles cover bringing OpenTelemetry profiling into Parca and profiling NVIDIA CUDA workloads in Kubernetes. Alongside his team’s participation in the OpenTelemetry Profiling Working Group, that work helps engineers trace performance problems down to the code consuming CPU and GPU resources.

Steven Callister

Steven Callister

Staff Site Reliability Engineer

Increasing SLO coverage means deciding what can be standardized without losing the judgment behind a useful objective. In an account of DoorDash’s approach, Steven describes that challenge from inside its site reliability engineering work.

The workflow combines automated SLO creation with engineering review and tuning. Explaining both parts gives other teams a practical example of expanding coverage while keeping people involved in deciding whether the resulting objectives describe the service well.

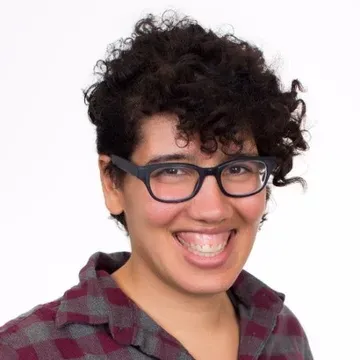
Julia Evans

Julia Evans

explaining computer things

wizard zines

Wizard Zines gives computer systems an approachable visual language. Julia’s explanations start with the details that can confuse a working engineer, including tools they may need urgently but use only occasionally.

Her work on examples for the dig and tcpdump man pages brings that teaching instinct into everyday troubleshooting. Making those examples easier to follow lowers the barrier to investigating DNS and network behavior when an engineer needs answers from the system itself.

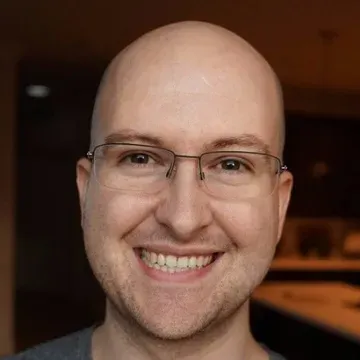
Heinrich Hartmann

A sample of traces can look precise while leaving considerable uncertainty about the system it represents. Heinrich brings that mathematical question into reliability practice through his talks, tools and work founding Signals Conference.

His tracing sampling calculator makes sampling error something engineers can explore directly. Connecting the calculation to operational measurement helps practitioners judge how much confidence to place in the numbers behind a reliability decision.

Laurent Querel

Laurent Querel

Sr Director and Distinguished Engineer

Telemetry has its own engineering costs: representing, moving and processing the data can shape the observability system built on top of it. Laurent works on those foundations through OpenTelemetry alongside his engineering leadership at F5.

His contributions to the collaborative OTel-Arrow effort explain the path from efficient transport to telemetry pipelines. Conference work on semantic conventions adds another part of the picture: data needs a consistent meaning if engineers are to use it to understand their systems.

Julius Volz

A target that disappears from Prometheus can leave an engineer debugging the monitoring before they can debug the service. Through PromLabs, Julius teaches the configuration details that determine what operators can see.

His explanation of relabeling visualization in Prometheus 3.8.0 makes those rules inspectable. Showing how a target changes as rules are applied turns an opaque configuration problem into a sequence engineers can follow and reason about.

Albert Wang

Albert Wang

Senior Staff Technical Lead Manager, Production Engineering

From a single Linux host to an entire region, Albert’s public work spans very different scales of failure. His role in Uber’s Production Engineering organization places those questions in the context of services that must keep operating when infrastructure becomes unhealthy.

His Linux memory guide gives engineers a starting point for interpreting memory pressure, while his conference work explains how Uber validates regional failover. Together, they make reliability concrete at both ends: understanding the signals on a machine and testing whether the wider system can recover.

Jimmy Zelinskie

Jimmy Zelinskie

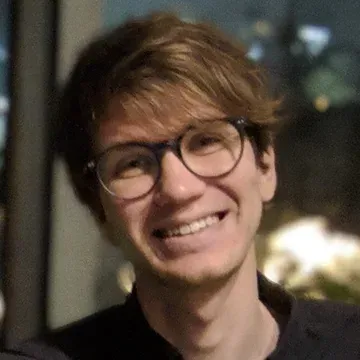
Co-Founder

Open-source infrastructure has been a constant in Jimmy’s career, from cloud-native projects at CoreOS and Red Hat to co-founding Authzed. Today, his work centers on SpiceDB, the authorization database inspired by Google’s Zanzibar, and the challenge of checking permissions reliably as applications grow.

He also maintains Open Container Initiative standards, contributing to the shared foundations that container tools depend on. Across that work, he combines experience building infrastructure with the product decisions that help other engineering teams adopt and operate it.

Building dependable infrastructure

People making infrastructure more reproducible, safer to change and easier to operate.

Darryl Balderas

Darryl Balderas

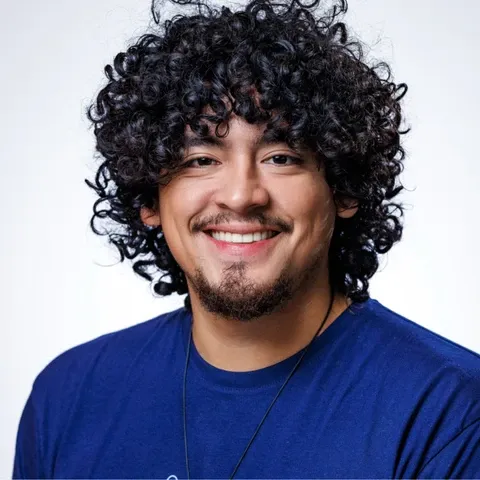
Senior software engineer

Building software at Latitude AI is one part of Darryl’s engineering life; outside work, he builds and shares projects with open-source infrastructure tools. His interests span cloud systems, Python, Go, and the physical machines underneath a Kubernetes cluster.

His bare-metal provisioning guide documents a system he can tear down and rebuild at home. Using Tinkerbell, Talos, Ansible, and Flux, he automates the path from a newly provisioned machine to running services, showing how the configuration and recovery process fit together.

Marcelo Iriarte

Marcelo Iriarte

Staff Platform Engineer

Delivery Hero

Cloud migrations put technical dependencies and human ownership on the same critical path. Marcelo’s shared lessons bring that operational perspective to the infrastructure changes he discusses alongside his platform engineering work at Delivery Hero.

He works through dependency mapping, database sequencing, traffic validation and the retirement of old infrastructure. Following the migration beyond the initial move makes the full responsibility visible, including how a team establishes that the new environment is ready to stand on its own.

Jessica Johnson

Jessica Johnson

Senior Director, Site Reliability Engineering

Major League Baseball (MLB)

A baseball game cannot wait for a production system to catch up. MLB’s reliability work spans live data for fans and technology used on the field, giving Jessica’s SRE leadership a deadline that is visible with every play.

In Reliability in the Big Leagues, presented with Chris Alexander, she shares how their team built an SRE practice around service-level objectives, psychological safety and operational trust. Her Operational Excellence program brings SLOs and incident data into leadership conversations, connecting the technical signals with the people who decide where reliability work happens next.

Thomas Khalil

Thomas Khalil

Head of Hybrid Platform & Developer Experience

Reliable access to internal systems matters across trivago’s distributed workforce. Thomas leads hybrid platforms and developer experience there, with responsibility for the infrastructure engineers use to build and operate the hotel-search service.

When his team replaced its VPN with Tailscale, the improvements were tangible: fewer dropped connections, faster access, and less maintenance. In sharing that experience, Thomas describes platform quality in terms colleagues recognize, from connecting without repeated restarts to reducing the effort needed to keep everyday tools working.

Aaron Mell

Aaron Mell

Staff SRE

Lumin Digital

Eight years as a developer and architect preceded Aaron’s move into SRE. He went on to help build Lumin Digital’s platform from the ground up, bringing software development experience to the infrastructure behind its digital banking services.

Kubernetes, deployment pipelines, and infrastructure automation are recurring parts of that work. His background covers both writing applications and operating them, with experience managing the release tooling that carries changes into production.

Ian Miller

Ian Miller

Platform Engineer

More than a decade in software engineering has taken Ian from backend development at Percolate to SRE at Seismic and now platform engineering at Alephic. His experience spans microservices migrations, Kubernetes, and the shared infrastructure that helps teams operate their own services.

His approach to reliability gives service teams the tools to own what they run, from setting SLOs and sharing on-call responsibilities to building their own observability. He also brings experience evaluating AI development tools and helping engineers adopt them within their existing workflows.

Niall Murphy

Niall Murphy

Author

Site Reliability Engineering, 2nd Edition

SRE became easier to teach when practitioners put its principles into books that other teams could use. Niall helped do that as a co-editor of Site Reliability Engineering and The Site Reliability Workbook, bringing operational experience into a shared body of guidance on service-level objectives, toil, incident response and how reliability teams work.

The new second edition of Site Reliability Engineering carries that work into a changed production landscape. With Niall among its credited authors and editors, it examines both how SRE supports AI systems and how AI can support SRE. His contribution spans the original foundations, the Workbook’s practical examples and this latest revision: helping engineers build a reliability practice that evolves with the systems they operate.

Qasim Raza

Qasim Raza

Reliability Engineer

A background in network software and test automation informs Qasim’s reliability work at Canva. Before moving into this role, he built experience in quality assurance, continuous delivery, and the infrastructure needed to test network behavior.

His toolkit spans Python, Jenkins, and Terraform, supported by a master’s degree in telecommunications from UNSW. That combination brings knowledge of both networks and software testing to the operational demands of a collaborative design platform.

James Renaud

James Renaud

Senior Staff Developer, Platform & Enablement

Helping engineers spend their time well is part of James’s work in platform enablement at Jane App. As a senior technical leader, he has been putting AI tools to use in his own day-to-day work and sharing what changes when routine implementation takes less time.

His architecture-documentation project is one example: using AI to assemble exported system diagrams into a browsable site. In his writing, he connects those decisions to the responsibilities of staff developers, including making room for coaching, mentoring, and work that needs their judgment.

Mark Shaw

Mark Shaw

Staff SRE

Making services easier to build and operate has been a recurring part of Mark’s work, from developer enablement at PagerDuty to SRE at Faire. His experience spans internal platforms and the production systems those platforms support.

At PagerDuty, he introduced Backstage during a hack week to help engineers create services from shared templates. The team adopted that starting point as its developer portal, an example of his contribution to the tools engineers use before a service ever reaches production.

Leila Vayghan

Leila Vayghan

Senior Site Reliability Engineer

Sometimes the strongest infrastructure decision is to leave a sophisticated optimization unbuilt. At Shopify, Leila works on the database capacity needed to keep commerce running through flash sales, where cost efficiency has to coexist with predictable operations.

In The Optimization We Didn’t Build, she explains why the team chose a fixed-target scaling design over a more elaborate model based on historical traffic. Separating flash-sale safety from baseline provisioning reduced manual work and cleared the way for a broader right-sizing effort. Her account makes the tradeoff explicit: a small potential saving can be outweighed by years of operational complexity.

Denys Vitali

Denys Vitali

Senior Platform Engineer

At kaiko.ai, Denys builds the platform tools behind deployments across customers, clusters, and clouds. His work includes ArgoCD release workflows, end-to-end testing, and CI improvements, drawing on earlier experience in cloud security at Niantic and observability for more than 10,000 devices at Open Systems.

He also contributes fixes upstream to projects including Prometheus Operator and Jaeger. That habit of working on the underlying tools runs through his personal writing, where he documents networking configurations and the tradeoffs involved in securing access to services.

Natali Vlatko

Natali Vlatko

Director of Open Source Software Engineering, OSPO

Documentation is part of the infrastructure people rely on to operate Kubernetes. Natali helps maintain that foundation as a Kubernetes SIG Docs co-chair, alongside directing open-source software engineering at Cisco. Her work connects the technical project with the contributors who make it understandable.

In Bridge the Gap to OSS Adoption with Documentation, presented with Divya Mohan, she brings that maintenance experience to the practical problem of helping people use open-source systems. Her participation in the TODO Group’s steering committee extends the same focus to how organizations support open-source work, making shared knowledge and sustained contribution part of the engineering practice.

Trisha Weir

Trisha Weir

Global Management Lead, Fleet SRE

Capacity planning becomes a reliability problem when changing demand leaves teams constantly rebuilding their plans. Trisha helped explain a different approach in the Google SRE book: encode what a service needs, then let software work out how to allocate the resources. Her coauthored chapter, Software Engineering in SRE, makes the case for treating operational tools as maintained software products, grounded in the experience of the engineers who run production.

Today, she leads global Fleet SRE management at Waymo, bringing that infrastructure perspective to autonomous driving. Her chapter’s Auxon case study remains a concrete example of how to make operational complexity manageable: capture dependencies, performance requirements and redundancy constraints, then regenerate capacity plans as conditions change. It gives other reliability teams a practical way to think beyond manual allocations and build systems that can adapt.

Dennis Zhang

Dennis Zhang

Senior Site Reliability Engineer

Keeping Gorgias running brings database behavior and incident coordination into the same engineering story. Dennis’s account describes how the team addressed bottlenecks and organized data as the service grew.

Connection-pool isolation, partitioning and incident roles are among the details he shares. The value comes from seeing the team’s choices together: changes to the system itself, alongside the practices people need when that system develops a problem.

Mikhail Zhilin

Mikhail Zhilin

Senior Software Engineer II, Observability

The move between two configurations can introduce failure modes that neither endpoint makes obvious. Mikhail’s operational accounts examine that transition alongside his observability engineering work at DigitalOcean.

His discussion of a Kubernetes secret-encryption rollout pays attention to resource limits, intermediate states and recovery. Sharing those details helps other platform engineers consider what happens during a change, including the demands it places on the infrastructure used to observe it.

The 2025 edition

Good work travels.

Follow a new voice. Share a useful talk. Bring an idea back to your team. Explore the people and work that started the Reliability Top 50.

Meet the 2025 Top 50 →

Your privacy choices

Rootly uses cookies from advertising partners to measure our ads and to show ads for Rootly on other sites. Some US state laws call that selling or sharing personal information. You can opt out of it for this browser here.

Analytics we use to improve this site stay on. Read Rootly's Privacy policy for more information.